In daily use · legal
Legal document intelligence
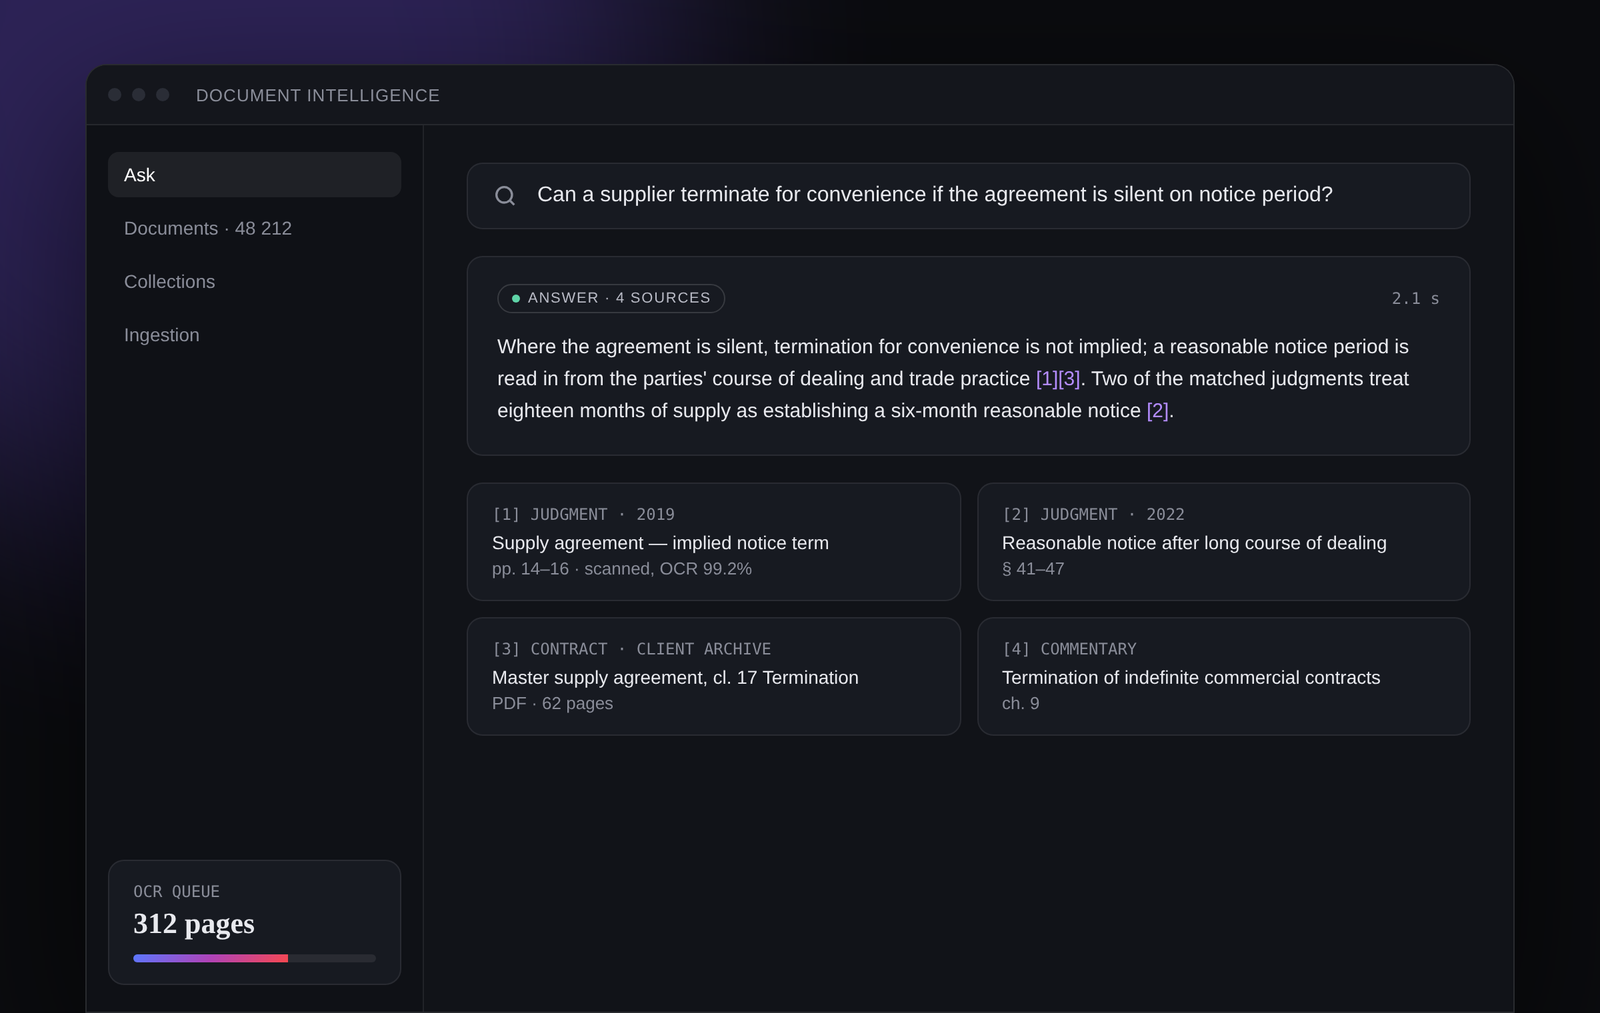
The situation. A legal team with tens of thousands of documents — contracts, judgments, whole archives of scans — and questions that took hours of reading to answer.
What we built. An ingestion pipeline that reads everything, scans included, a search engine of our own on Postgres, and question-answering that cites the exact page it drew on. Expensive models only where they earn their keep.
What it changed. Lawyers ask in plain language and get an answer with verifiable sources in seconds. In daily production use since launch, maintained and improved continuously.
Made of: OCR at scale · PostgreSQL search · tiered language models · cloud containers